

IBM Spectrum Scale is part of a suite of Software defined storage products that provides a unified interface for storage management.
The Spectrum Scale (GPFS/TigerShark) is a high-performance object storage scale-out clustered file system for managing unstructured files developed by IBM that provides concurrent access to a file . It can be deployed in shared disk configurations allowing us to configure high available file system allowing concurrent access from a cluster of nodes thus offering parallelism and guaranteed availability at all times.
Overcoming Single-Point-of-Failure in Traditional NFS
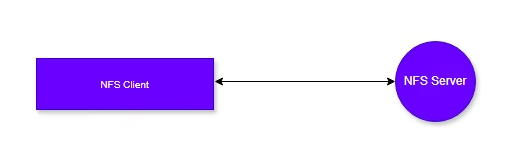
In a typical NFS server model, each client connects to a single NFS server to access data. While simple, this setup has a major drawback: the server is a single point of failure. If the server goes down, clients lose access to their data, and performance can become a bottleneck.
How IBM Spectrum Scale Solves This
IBM Spectrum Scale eliminates this issue by spreading data across multiple nodes, called NSD nodes. Key benefits of this architecture include:
- No single point of failure: If one node goes down, other nodes continue serving data.
- Maximum throughput: Data can be read and written in parallel across multiple nodes.
- Scalable capacity: Adding more NSD nodes increases storage capacity and performance simultaneously.
By distributing both data and access across multiple NSD nodes, Spectrum Scale provides high availability, high performance, and true scalability, addressing the limitations of traditional NFS systems.
Features of Scale System
- Storage Tiering
- Container Native Storage
- Data replication
- Policy Based Storage Management
- Multi-site operations
All GPFS management utilities are located under the /usr/lpp/mmfs/bin/ directory and commands typically start with mm(multimedia)
The NSD Model of Spectrum Scale
The architecture of IBM Spectrum Scale is built around Network Shared Disks (NSDs) and parallelism, which together enable high performance, scalability, and efficient access to unstructured data.
Network Shared Disks (NSDs)
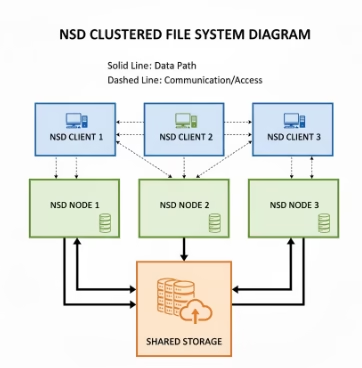
- NSD Nodes: A node is called an NSD node when it provides access to storage for other nodes in the cluster. These nodes act as the storage access points.
- NSD Clients: Other nodes, called NSD clients, request data from the NSD nodes. The NSD node serves the requested data, enabling efficient data sharing across the cluster.
Parallelism
This breaks data and put its on all storage systems thus offering parallel data access across multiple NSD nodes and disks. This ensures:
- High throughput for large-scale workloads
- Low latency access even under heavy demand
- Scalable performance as more nodes or disks are added
The advantage of parallelism is that unlike the traditional way data is fetched sequentially, here data can be be obtained in parallel way offering a very high bandwidth reducing response times.
Software Deployment Options
The Spectrum Scale can be deployed in three ways
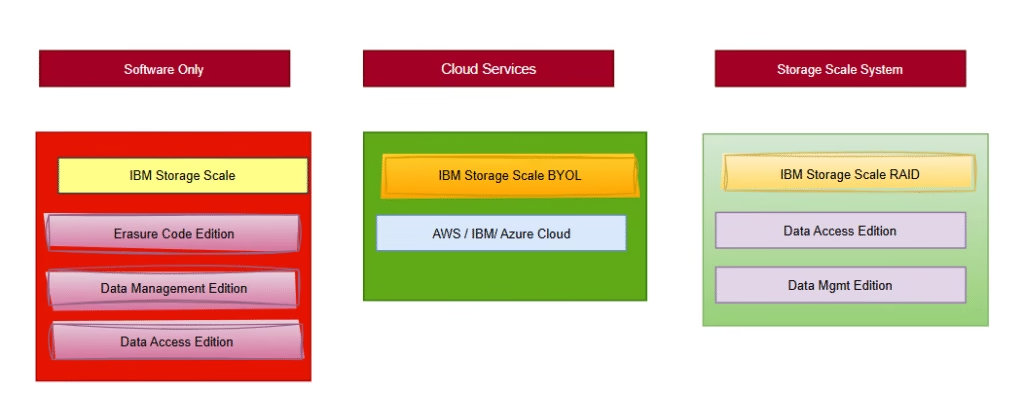
Deployment Options of NSD
The NSD can be deployed in 3 ways and the most commonly used one is the shared disk cluster model.
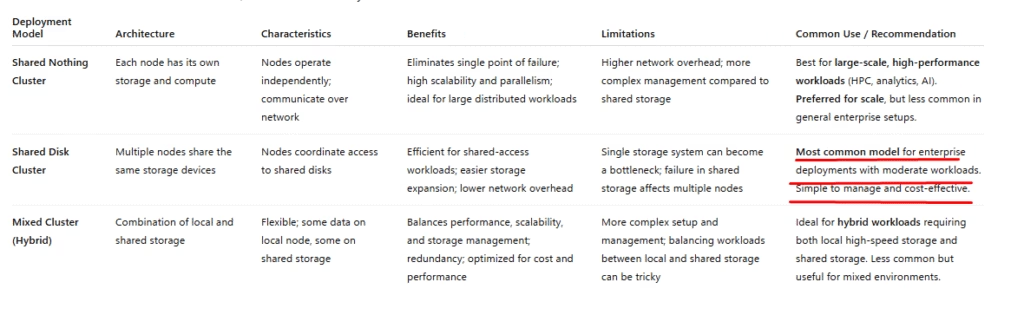
Diagram showing NSD clients, NSD nodes, and shared storage
There exist another deployment model IBM Elastic Storage Server which is covered in our next blog.